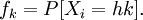Tag Archives: Computer

Tests statistiques et p value

Mercredi, nous avons abordé le concept de http://freakonometrics.blog.free.fr/public/perso2/testic-10.gif-value en cours (avant de parler tout à l’heure de tests asymptotiques). Intuitivement, la http://freakonometrics.blog.free.fr/public/perso2/testic-10.gif-value est la probabilité que la statistique de test prenne une valeur au moins aussi extrême que celle qui a été observée, si l’hypothèse http://freakonometrics.blog.free.fr/public/perso2/testp-08.gif est vraie.

  • Fisher vs. Neyman (et Pearson)

Dans l’approche de Fisher, on suppose que http://freakonometrics.blog.free.fr/public/perso2/testp-01.gif et on cherche à tester http://freakonometrics.blog.free.fr/public/perso2/TEST-REGION-01.gif. On dispose pour cela d’un échantillon http://freakonometrics.blog.free.fr/public/perso2/testp-02.gif.
On choisit une statistique http://freakonometrics.blog.free.fr/public/perso2/testp-03.gif telle que plus http://freakonometrics.blog.free.fr/public/perso2/testic-5.gif est grande, plus on s’éloigne de http://freakonometrics.blog.free.fr/public/perso2/testp-08.gif (on calcule une distance à l’hypothèse http://freakonometrics.blog.free.fr/public/perso2/testp-08.gif, quelque chose comme ça). On calcule alors la http://freakonometrics.blog.free.fr/public/perso2/testic-10.gif-value comme

http://freakonometrics.blog.free.fr/public/perso2/testp-07.gif

et on rejette http://freakonometrics.blog.free.fr/public/perso2/testp-08.gif si http://freakonometrics.blog.free.fr/public/perso2/testic-10.gif est trop petite. La notion de “plus petite” est liée à la comparaison avec un seuil prédéfini, souvent 5% (cf plus loin pour une discussion).
C’est un peu heuristique, mais c’est comme cela que ça fonctionne.
Dans l’approche de Neyman-Pearson, on cherche à testerhttp://freakonometrics.blog.free.fr/public/perso2/TEST-REGION-01.gif contre une hypothèse alternative, du genre http://freakonometrics.blog.free.fr/public/perso2/testp-11.gif. Si http://freakonometrics.blog.free.fr/public/perso2/testp-12.gif, on va construire une région de rejet de la forme

http://freakonometrics.blog.free.fr/public/perso2/testp-13.gif

où http://freakonometrics.blog.free.fr/public/perso2/testp-14.gif est choisi en fonction d’une probabilité d’erreur de première espèce souhaitée a priori, i.e.

http://freakonometrics.blog.free.fr/public/perso2/testp-15.gif

Par exemple, considérons un échantillon suivant une loi http://freakonometrics.blog.free.fr/public/perso2/testp-16.gif. On dispose de http://freakonometrics.blog.free.fr/public/perso2/testp-17.gif observations pour tester http://freakonometrics.blog.free.fr/public/perso2/testp-20.gif. L’échantillon est le suivant

> set.seed(4)
> (X=rnorm(10))
 [1]  0.2167549 -0.5424926  0.8911446  0.5959806  1.6356180  0.6892754
 [7] -1.2812466 -0.2131445  1.8965399  1.7768632

La statistique proposée par Fisher (je ne discuterais pas le choix optimal de la statistique – si quelqu’un a des références, les commentaires sont ouvertes) est la moyenne normalisée,

http://freakonometrics.blog.free.fr/public/perso2/testp-21.gif

On sait que sous H_0, cette statistique suit une loi normale centrée réduite.  La http://freakonometrics.blog.free.fr/public/perso2/testic-10.gif-value se calcule alors simplement

> (T=sqrt(10)*mean(X))
[1] 1.791523
 
> 2*(1-pnorm(T,mean=0,sd=0)))
[1] 0.07320942

Graphiquement, cela se représente de la manière suivante.

Cette probabilité étant faible, on aurait tendance vouloir rejeter http://freakonometrics.blog.free.fr/public/perso2/testp-20.gif.
Dans l’optique de Neyman Pearson, si on teste http://freakonometrics.blog.free.fr/public/perso2/testp-20.gif contre http://freakonometrics.blog.free.fr/public/perso2/testp-22.gif, la région critique s’obtient à l’aide du rapport de vraisemblance

http://freakonometrics.blog.free.fr/public/perso2/testp-25.gif

ou encore

http://freakonometrics.blog.free.fr/public/perso2/testp-26.gif

ce qui se traduit par

http://freakonometrics.blog.free.fr/public/perso2/testp-27.gif

où http://freakonometrics.blog.free.fr/public/perso2/testp-14.gif est tel que

http://freakonometrics.blog.free.fr/public/perso2/testp-29.gif

Or sous H_0, la somme suit une loi normale centrée de variance http://freakonometrics.blog.free.fr/public/perso2/testp-30.gif. Ici, http://freakonometrics.blog.free.fr/public/perso2/testp-14.gif est donné par

> qnorm(1-alpha,mean=0,sd=sqrt(10))
[1] 5.201484

Or pour rappel, la somme vaut ici

> sum(X)
[1] 5.665293

On est dans la région de rejet: on rejette alors http://freakonometrics.blog.free.fr/public/perso2/testp-20.gif.

  • p-value pour les tests usuels de R

La http://freakonometrics.blog.free.fr/public/perso2/testic-10.gif-value est intéressante en pratique car elle permet à l’utilisateur de ne pas rentrer trop dans les détails de la construction du test, et de la loi de la statistique considérée.
Par exemple (comme celui abordé ici), pour un test d’égalité de proportion, sous R, la commande est

> prop.test(nx,n,.5)
 
1-sample proportions test with continuity correction
 
data:  nx out of n, null probability 0.5
X-squared = 0.05, df = 1, p-value = 0.823
alternative hypothesis: true p is not equal to 0.5
95 percent confidence interval:
0.3204804 0.7617145
sample estimates:
p
0.55

Et de manière générale, tous les tests sous R renvoient une http://freakonometrics.blog.free.fr/public/perso2/testic-10.gif-value.

  • p ne signifie pas puissance

(mais probabilité). Dans un test simple,http://freakonometrics.blog.free.fr/public/perso2/TEST-REGION-01.gif contrehttp://freakonometrics.blog.free.fr/public/perso2/testh13.gif, la puissance est la probabilité de rejeter http://freakonometrics.blog.free.fr/public/perso2/test-H0.gif sous l’hypothèse où http://freakonometrics.blog.free.fr/public/perso2/H1.gif est vraie (rejeter http://freakonometrics.blog.free.fr/public/perso2/test-H0.gif avec raison si on veut). C’est donc une fonction de  http://freakonometrics.blog.free.fr/public/perso2/testh14.gif.
Pour un test multiple, avec une hypothèse alternative de la forme http://freakonometrics.blog.free.fr/public/perso2/testp-36.gif, on définit alors une fonction puissance pour toute valeur  http://freakonometrics.blog.free.fr/public/perso2/testh14.gif.  On a alors des graphiques de fonction puissance, comme ceux évoqués ici. Bref, la http://freakonometrics.blog.free.fr/public/perso2/testic-10.gif-value est une valeur, alors que la puissance sera une fonction, définie sur http://freakonometrics.blog.free.fr/public/perso2/testp-40.giflorsque H_1 est une hypothèse de la forme http://freakonometrics.blog.free.fr/public/perso2/testp-41.gif.

  • L’interprétation de p

La http://freakonometrics.blog.free.fr/public/perso2/testic-10.gif-value est la probabilité d’obtenir (au moins) la statistique obtenue pour l’échantillon si http://freakonometrics.blog.free.fr/public/perso2/test-H0.gif est vraie. Classiquement, on rejette http://freakonometrics.blog.free.fr/public/perso2/test-H0.gif si la http://freakonometrics.blog.free.fr/public/perso2/testic-10.gif-value est inférieure au seuil http://freakonometrics.blog.free.fr/public/perso2/testh04.gif .
Certains interprètent la http://freakonometrics.blog.free.fr/public/perso2/testic-10.gif-value comme la probabilité que http://freakonometrics.blog.free.fr/public/perso2/test-H0.gif est vraie, http://freakonometrics.blog.free.fr/public/perso2/testp-55.gif. Ce qui n’a pas de sens si l’on s’en tient au formalisme énoncé en cours: http://freakonometrics.blog.free.fr/public/perso2/test-H0.gif est vraie, ou pas.
Ce n’est pas non plus la probabilité de rejeter, à tort, http://freakonometrics.blog.free.fr/public/perso2/test-H0.gif , http://freakonometrics.blog.free.fr/public/perso2/testp-57.gif, correspondant à la puissance du test (cf la discussion dans le paragraphe précédant).

  • Pourquoi 5% ?

En pratique, on prend toujours comme valeur critique 5%, avec la règle décision simple suivante:

  • http://freakonometrics.blog.free.fr/public/perso2/testp-65.gif: si http://freakonometrics.blog.free.fr/public/perso2/testp-61.gif on accepte http://freakonometrics.blog.free.fr/public/perso2/test-H0.gif
  • http://freakonometrics.blog.free.fr/public/perso2/testp-66.gif: si http://freakonometrics.blog.free.fr/public/perso2/testp-60.gif on rejette http://freakonometrics.blog.free.fr/public/perso2/testp-33.gif

C’est Fisher qui semble être à l’origine de ce 5%, en 1925 “The value for which P=0.05, or 1 in 20, is 1.96 or nearly 2; it is convenient to take this point as a limit in judging whether a deviation ought to be considered significant or not. Deviations exceeding twice the standard deviation are thus formally regarded as significant. Using this criterion we should be led to follow up a false indication only once in 22 trials, even if the statistics were the only guide available.” On retrouve ce “un sur vingt” un an plus tard, “Either there is something in the treatment, or a coincidence has occurred such as does not occur more than once in twenty trials”.
Voilà ce que l’on retient souvent de la lecture des conseils de Fisher.
Maintenant, il lui arrive aussi, à l’occasion, de penser que 4% ce n’est pas significatif, e.g. “P is between .02 and .05. The result must be judged significant, though barely so; in view of the data we cannot ignore the possibility that on this field, and in conjunction with the other manures used, nitrate of soda has conserved the fertility better than sulphate of ammonia; the data do not, however, demonstrate this point beyond the possibility of doubt.” Ou parfois pense que 8% est significatif “P=.089. Thus a larger value of 2 would be obtained by chance only 8.9 times in a hundred, from a series of values in random order. There is thus some reason to suspect that the distribution of rainfall in successive years is not wholly fortuitous, but that some slowly changing cause is liable to affect in the same direction the rainfall of a number of consecutive years.”

Marc Levy n’utilise que 150 mots ?

L’intérêt des voyages en avion, c’est que ça offre beaucoup de temps pour lire… Et comme j’avais fini mon polar arrivé à Paris, je me suis rabattu sur la version papier de Rue89. Et un article m’a beaucoup plus, où l’on apprenait que les hommes ne pouvaient pas lire Marc Levy… Ne l’ayant jamais lu moi même je ne suis pas apte pour juger, mais une raison évoquée était qu’il utilisait trop peu de mots… En particulier, l’article reprenait une déclaration de François Busnel qui affirmait (ici) “Ces livres sont cousus de fil blanc et écrits avec 150 mots. C’est comme la série Les Feux de l’amour.”

Ah, voilà une affirmation qui m’intéresse en tant que statisticien… combien les écrivains utilisent de mots dans leurs romans…?

Si on regarde Le Voleur d’Ombre, il contient environ 64 000 mots, en tout. Parmi ces mots, on en compte 6 830 uniques (en sachant qu’ici abandonnèrent,abandonne et abandonnait, par exemple, sont considérés comme différents). Le code R est d’ailleurs assez simple,

> livre=scan("Levy-Marc-Le voleur d'ombres.txt", 
+ what=character())
> minlivre=tolower(livre)
> TABLE=rev(sort(table(minlivre)))
> length(TABLE)
[1] 6827
> length(livre)
[1] 64122
> D1=data.frame(mot=names(x),N=as.numeric(x),
+ Freq=as.numeric(x)/sum(x)*100)

(je tiens à préciser que j’ai remplacé les virgules, les points, les apostrophes, etc par des espaces, dans le texte de base afin de récupérer dans le fichier simplement des mots, sans symboles – et j’ai transformé les mots pour n’avoir que des minuscules).

Histoire de comparer avec d’autres auteurs, j’ai pris un auteur plus ancien (pour éviter les soucis de droits d’auteurs, car les textes se trouvent en ligne), à savoir Théophile Gautier, et plus particulièrement son Capitaine Fracasse (oui, on reste dans les pavés). En tout, 127 177 mots, dont 15 595 uniques. Si on compare les courbes de Lorentz, on obtient le graphique suivant,

Les 20 mots les plus fréquents sont (en nombre et surtout en fréquence) respectivement

cbind(D1[1:20,],D2[1:20,])
    mot    N      Freq mot    N      Freq
1    de 2310 3.6025077  de 6284 4.9411450
2    la 1591 2.4812077  et 3862 3.0367126
3    je 1534 2.3923147  la 3720 2.9250572
4     à 1270 1.9805995  le 3235 2.5436989
5    le 1165 1.8168491   à 2429 1.9099365
6    et 1121 1.7482299 les 2214 1.7408808
7   que 1096 1.7092418   d 2192 1.7235821
8     j  889 1.3864196  un 2075 1.6315843
9     l  873 1.3614672   l 2055 1.6158582
10   un  857 1.3365148 une 1678 1.3194210
11   en  780 1.2164312  en 1497 1.1770996
12   me  736 1.1478120  il 1494 1.1747407
13  pas  701 1.0932285 des 1455 1.1440748
14  les  665 1.0370856  se 1178 0.9262681
15   il  654 1.0199308 que 1085 0.8531417
16 elle  653 1.0183712  du 1072 0.8429197
17   tu  596 0.9294782 qui 1064 0.8366293
18   ai  588 0.9170020 son  971 0.7635028
19 dans  549 0.8561804   s  922 0.7249739
20    d  542 0.8452637  qu  915 0.7194697

On retrouve malgré tout que Marc Levy utilise une autre manière d’écrire, qu’il utilise beaucoup le je ou le moi (par rapport à Théophile Gautier). Mais critiquer car il utilise peu de mots me semble un peu léger…. il semble en utiliser autant que des vrais grands écrivains….

Comments on probabilities

The only thing I remember from courses I had in probability a few years ago is that we also have to clearly defined the event we want to calculate the probability. On the Freakonomics blog, last week, the Israeli lottery was mentioned (here, see also there where I mentioned that, and odds facts from the French lottery),

Yesterday, Andrew Gelman claimed (here) that there was a probability error… Well, since Andrew is really a statistician (and a good one… while I am barely an economist), I tried to do the maths…. and to understand where the error was coming from…

Since 6 numbers are drawn out of a pool of numbers from 1 to 37, the total number of combination at each lottery is

https://perso.univ-rennes1.fr/arthur.charpentier/latex/loto01.png
> (n=choose(37,6))
[1] 2324784

Over 8 lotteries (since there are two draws per week, we can assume there 8 draws per month), the probability of no identical draws is

https://perso.univ-rennes1.fr/arthur.charpentier/latex/loto02.png

Here is the R code for those who want to check, again,

> prod(n-0:7)/n^8
[1] 0.999988

Each month, the probability of “coincidence” (I define “coincidence” the event “over 8 draws, at least two times, we obtained the same 6-uplet” or more precisely (as mentioned here) “over one calendar month, at least two times, we obtained the same 6-uplet“) is

> (p=1-(prod(n-0:7)/n^8))
[1] 1.204407e-05

The occurrence of a coincidence each month as a Geometric distribution, with probability p. And it is classical, following Gumbel’s definition (here), to consider 1/p, called the “return period“, i.e. the number of months we have to wait until we observe a coincidence (i.e. a repetition in the same month), since for a geometric distribution

https://perso.univ-rennes1.fr/arthur.charpentier/latex/loto03.png
> 1/p/(12)
[1] 6919.034

Here, the (expected) return period is 6919 years.

From my point of view, this is “the incident of six numbers repeating themselves within a calendar month”, and this is an event of once in 6919.034 years. On the other hand the median of a geometric distribution is

https://perso.univ-rennes1.fr/arthur.charpentier/latex/loto04.png
> -log(2)/log(1-p)/(12)
[1] 4795.88

which means that we have 50% chance to get such a coincidence over 4796 years.

Of course, if instead of looking at a longer period, say 100 draws, i.e. one year (here I define “coincidence” the event “over 100 draws, at least two times, we obtained the same 6-uplet“), we have in red the expected return period, and in blue the median of the geometric distribution,

> M=E=rep(NA,100)
> for(i in 2:100){
+ p=1-exp((sum(log(n-0:(i-1)))-i*log(n)))
+ E[i]=1/p/(100/i)
+ M[i]=-log(2)/log(1-p)/(100/i)
+ }
> plot(1:100,E,ylim=c(0,10000),type="l",col="red",lwd=2)
> lines(1:100,M,col="blue",lwd=2)
> abline(v=8,lty=2)
> points(8,E[8],pch=19,col="red")
> points(8,M[8],pch=19,col="blue")

or below of a log-scaled version

As Xi’an did (here), assume now that there is a lottery over 100 countries. Here I define “coincidence” the event “over k lottery draws over 100 around the world, at least two times, we obtained the same 6-uplet“, and then the previous graph becomes (with on the x axis the level of k)

Here I have a 12% chance if we consider probability to have identical numbers over a month…

But here, we can have one 6-uplet in Israel, and the other one in Egypt, say… If we want to get the same 6-uplet in the same country, the graph is now

i.e. each month there is a chance over one thousand…

> i=8
> p=1-exp((sum(log(n-0:(i-1)))-i*log(n)))
> 1-(1-p)^100
[1] 0.001203689

Note: actually, Xi’an mentioned that the probability that this coincidence [of two identical draws over 188 draws] occurred in at least one out of 100 lotteries (there are hundreds of similar lotteries across the World) is 53%! And I got the same,

> 1-(1-P[188])^100
[1] 0.5305219

MacGyver et la théorie des groupes

L’autre jour, quelqu’un me félicitait pour mon blog, c’était une étudiante en maths, qui disait comprendre certaines choses en probas et en stats (entre autres sur les applications possibles)…. mais pour la théorie des groupes, elle ne voyait toujours pas d’intérêt…

J’étais bien entendu ravi que mon blog serve à quelque chose, mais en fait la théorie des groupes peut avoir des applications amusantes (bon, tout dépend aussi de ses centres d’amusement). Par exemple MacGyver pourrait avoir eu besoin de connaître des résultats sur les groupes pour sortir des prisonniers des geôles afghanes…

Considérons le gardien de prison sadique qui annonce le “jeu” suivant (Anatole, un collègue ici me l’avait suggéré l’autre jour en me mettant au défi de trouver une solution…. mais faut pas pousser, je suis plus fort que MacGyver ! bon, et il faut dire que le jeu est classique…on le trouve expliqué ici ou là):

Tous les prisonniers (disons qu’ils sont 20) se voient attribuer un numéro, entre 1 et 20. Le premier prisonnier est appelé et se retrouve face à 20 portes, derrière lesquelles sont cachés des numéros (allant de 1 à 20 là encore). Il a droit d’en ouvrir 10 (au maximum) et il doit retrouver son numéro. S’il n’y arrive pas,tous les prisonniers sont exécutés (lui compris). S’il y arrive, il n’est pas sauvé pour autant car le commandant appelle le second prisonnier, qui se retrouve à son tour devant les 20 portes, et doit trouver son numéro… Etc.

Les prisonniers commencent à paniquer, car tout le monde doit trouver son numéro pour être sauvé. En raisonnant rapidement, un des prisonniers explique qu’un seul prisonnier aurait 50% de chances d’y arriver. Avec deux, comme ils ont tous les deux 50% de chances, on tombe à 25%, etc. Avec n prisonniers, on est à 1/2n, qui est de l’ordre d’une chance sur un million avec 20 prisonniers…. Et qu’ils ont de la chance de n’être que 20 ! Avec 30 prisonniers, ils
auraient une chance sur un milliard de s’en sortir (ce qui est faible, on en conviendra).

Mais MacGyver, qui avait pris le cours Théorie des Groupes 101 à l’université (et qui avait R installé dans sa montre digitale) dit

  • pas du tout, j’ai une stratégie qui nous donne environ une chance sur trois de tous s’en sortir (vu comme ça c’est pas terrible, mais par rapport à 1 chance sur un milliard, c’est vachement bien),
  • et accessoirement, cette probabilité ne dépend pas du nombre de prisonnier (tant que l’on puisse ouvrir moitié moins de portes qu’il y a de prisonniers)

Bon, sur le moment, les autres prisonniers se fichent du fait que même s’ils étaient 1000 ils auraient une chance sur trois de survivre, ils veulent comprendre la stratégie de Mac… Comme le rappelle Mac, le commandant ne fait que choisir une permutation de https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison99.png, même s’il est sadique (ou parce qu’il est sadique, les profs de maths sont sadiques, tout le monde sait ça). Et toute permutation peut se décomposer en un produit ds combinaisons cycliques (on parle de la décomposition en produit de cycles à supports disjoints, c’est un truc utilise je crois pour les amateurs de Rubik’s cube),

Par exemple, considérons la permutation suivante (c’est la première que j’ai eu sous R),

https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison01.png

Elle se décompose en 5 permutations cycliques

https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison02.png

La plus grande est la dernière, et elle permute sur 7 nombres. Autrement dit, si chacun utilise cette stratégie, il ouvrira au plus 7 portes. Le point important est qu’ils ne peuvent pas être pris dans une autre permutation que la leur, car ils ont pris leur porte, donc au pire, il tire le numéro de la première porte qu’ils ont ouvert… qui est le numéro qu’ils doivent tirer pour survivre ! Regardons sur notre exemple

> set.seed(1)
> portes = sample(1:n,size=n,replace=FALSE)
>  prisonnier=1
>  essai = c(prisonnier)
>  nessai = 1
>  i = porte[prisonnier]
>  while(nessai <= 50) {
+  essai = c(essai, i)
+  if(i == prisonnier) {
+  cat(“Le prisonnier”, prisonnier, “a ouvert”, nessai, “portes\n”)
+  break; }
+  else {
+  i = porte[i]}
+ n essai =n essai+1 }
Le prisonnier 1 a ouvert 4 portes
>  cat(“Le prisonnier”, prisonnier, “a ouvert les portes suivantes”, 
paste(essai[-length(essai)], collapse=” – “), “\n”)
Le prisonnier 1 a ouvert les portes suivantes 1 – 6 – 14 – 10

soit ici

Le prisonnier 1 a ouvert 4 portes
Le prisonnier 1 a ouvert les portes suivantes 1 – 6 – 14 – 10
Le prisonnier 2 a ouvert 7 portes
Le prisonnier 2 a ouvert les portes suivantes 2 – 8 – 9 – 19 – 18 – 17 – 12
Le prisonnier 3 a ouvert 2 portes
Le prisonnier 3 a ouvert les portes suivantes 3 – 11
Le prisonnier 4 a ouvert 5 portes
Le prisonnier 4 a ouvert les portes suivantes 4 – 16 – 7 – 15 – 5
Le prisonnier 5 a ouvert 5 portes
Le prisonnier 5 a ouvert les portes suivantes 5 – 4 – 16 – 7 – 15
Le prisonnier 6 a ouvert 4 portes
Le prisonnier 6 a ouvert les portes suivantes 6 – 14 – 10 – 1
Le prisonnier 7 a ouvert 5 portes
Le prisonnier 7 a ouvert les portes suivantes 7 – 15 – 5 – 4 – 16
Le prisonnier 8 a ouvert 7 portes
Le prisonnier 8 a ouvert les portes suivantes 8 – 9 – 19 – 18 – 17 – 12 – 2
Le prisonnier 9 a ouvert 7 portes
Le prisonnier 9 a ouvert les portes suivantes 9 – 19 – 18 – 17 – 12 – 2 – 8
Le prisonnier 10 a ouvert 4 portes
Le prisonnier 10 a ouvert les portes suivantes 10 – 1 – 6 – 14
Le prisonnier 11 a ouvert 2 portes
Le prisonnier 11 a ouvert les portes suivantes 11 – 3
Le prisonnier 12 a ouvert 7 portes
Le prisonnier 12 a ouvert les portes suivantes 12 – 2 – 8 – 9 – 19 – 18 – 17
Le prisonnier 13 a ouvert 2 portes
Le prisonnier 13 a ouvert les portes suivantes 13 – 20
Le prisonnier 14 a ouvert 4 portes
Le prisonnier 14 a ouvert les portes suivantes 14 – 10 – 1 – 6
Le prisonnier 15 a ouvert 5 portes
Le prisonnier 15 a ouvert les portes suivantes 15 – 5 – 4 – 16 – 7
Le prisonnier 16 a ouvert 5 portes
Le prisonnier 16 a ouvert les portes suivantes 16 – 7 – 15 – 5 – 4
Le prisonnier 17 a ouvert 7 portes
Le prisonnier 17 a ouvert les portes suivantes 17 – 12 – 2 – 8 – 9 – 19 – 18
Le prisonnier 18 a ouvert 7 portes
Le prisonnier 18 a ouvert les portes suivantes 18 – 17 – 12 – 2 – 8 – 9 – 19
Le prisonnier 19 a ouvert 7 portes
Le prisonnier 19 a ouvert les portes suivantes 19 – 18 – 17 – 12 – 2 – 8 – 9
Le prisonnier 20 a ouvert 2 portes
Le prisonnier 20 a ouvert les portes suivantes 20 – 13

En adaptant un code développé ici par Matt Asher, on peut d’ailleurs visualiser tout ça sur un petit dessin,
,

Bref, la grande question est “quelle est la probabilité que la plus grande sous permutation cyclique soit sur un ensemble de taille supérieure à 10” ? On peut faire un peu de Monte Carlo pour voir…. c’est ce que fait Matt. Mais sinon on peut aussi faire du dénombrement (ce qui est pareil que les probas). Le nombre de permutations contenant un cycle de longueur supérieure à 10 (strictement) se calcule de la manière suivante: soit k la taille du cycle, alors je peux choisir les https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison00.png nombres de https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison03.png manières. Il y a alors https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison04.png permutations circulaires de ces k nombres, et on permute les https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison05.png nombres qui reste comme on veut, ce qui donne https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison06.png possibilités. Bref, j’en suis à

https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison07.png

permutations ayant un cycle de longueur k, soit en tout,

https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison0_.png

Or comme on a en tout https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison08.png permutations possibles, la probabilité de s’en sortir vivant est

https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison09.png

Et là où Mac est fort, c’est qu’effectivement, avec n prisonniers

https://perso.univ-rennes1.fr/arthur.charpentier/latex/prison10.png

Soit environ 30% de chances de s’en sortir….
Moralité, la théorie des groupes peut être marrante et intéressante…. Bon, c’est la seule application à la vraie vie qui me vient à l’esprit, et à moins d’être enfermé en prison avec un geôlier sadique, c’est dur de trouver des applications. N’empêche que la solution est passionnante (mais MacGyver a toujours été mon héros pour ça…)

Lottery, and martingales

I recently got a comment on a post I published one year ago, here, about the fact that in September 2009, on the 6th and the 10th, the 6 same numbers came out at the lottery, in Bulgaria (but  I do not understand the question: the author of the comment ask about the order the numbers came out…)
Xi’an published also a post on that topic, there, since last week, the same thing happened in Israel.
All that reminded me a discussion I had with a colleague about another post (here) where I mentioned that I found a strange distribution of numbers in the French lottery (the old one actually). For those who want to check, all historical events are here, in a zip file. My colleague was wondering if I found the martingale to win the lottery…

First, I do not like that term, since martingale is something different from a mathematical point of view… Second, let us look if it would have been possible to make some money… (free lunch ?)

> loto=read.table("D:\\loto.csv",dec=",",header=TRUE,sep=";")
> ntirage=nrow(loto)
> loto=loto[51:ntirage,]
> ntirage=nrow(loto)
>   N=as.matrix(loto[,c("boule_1","boule_2","boule_3","boule_4","boule_5","boule_6")])
> n=as.vector(N)
> length(n)
[1] 28848
> (TN=table(n))
n
1   2   3   4   5   6   7   8   9  10  11  12  13  14  15  16  17  18  19  20
607 576 571 618 579 598 608 582 588 590 562 577 577 580 591 630 558 567 594 608
21  22  23  24  25  26  27  28  29  30  31  32  33  34  35  36  37  38  39  40
578 562 579 583 574 589 602 572 550 598 604 582 545 646 597 618 599 636 609 588
41  42  43  44  45  46  47  48  49
576 589 577 585 618 596 560 571 604

So, it might look nice, but we have to compare that distribution with the one we should have with “independent” draws. It is not possible to look at a discrete uniform distribution: the six numbers are not independent. Each day, the 49 balls are back in the urn, but within a day, we do not have independent draws (it is a sample without replacement of balls). Hence, with 4808 lottery draws, each number cannot be obtained more than 4808 times. So, let us use monte carlo techniques to  look at the theoretical distribution,

> M=matrix(NA,49,1000)
> for(s in 1:1000){
+ B=NA
+ for(i in 1:ntirage){B=c(B,sample(1:49,size=6,replace=FALSE))}
+ B=B[-1]
+ M[,s]=sort(table(B))
+ }
> q50=function(x){quantile(x,.5)}
> Q50=apply(M,1,q50)
> lines(1:49,Q50,col="red",lwd=2)
> q10=function(x){quantile(x,.1)}
> Q10=apply(M,1,q10)
> q90=function(x){quantile(x,.9)}
> Q90=apply(M,1,q90)
> polygon(c(1:49,49:1),c(Q10,rev(Q90)),col="light blue",border=NA)
> lines(1:49,Q10,col="red",lty=2)
> lines(1:49,Q90,col="red",lty=2)
> lines(1:49,Q50,col="red",lwd=2)
> points(1:49,sort(TN),pch=19,type="b")

Looking at the graph, it looks like some numbers appeared too frequently, especially the ones that did not appear frequently (bottom left). So, since I have removed the last 50 draws, let us see if we could have used that information, somehow…

> nb=names(sort(TN))
> loto=read.table("D:\\loto.csv",dec=",",header=TRUE,sep=";")
> loto=loto[1:50,]
> N=as.matrix(loto[,c("boule_1","boule_2","boule_3","boule_4","boule_5","boule_6")])
> n=as.vector(N)
> TN=table(n)
> TN[nb]
> barplot(TN[nb])

Unfortunately, numbers that came out too frequently over 4800 draws did not appear that frequently of the last 50. Playing top number might not have been a great strategy.

(numbers that came out frequently are on the right, while those we did not see much are on the left)… What about worst numbers: if I had decided to play the 6 that did not come out very frequently (we’ve seen earlier that they should have appeared even less, actually), would it have been interesting ? As we can see, our top 2 numbers were numbers that did not appear frequently earlier (29 and 47 appears respectively 10 and 11 times over 50 draws)….
Over 50 draws of 6 balls, the expected frequency of 6 given number is around 36.7,..

> S=rep(NA,10000)
> for(s in 1:10000){
+ B=NA
+ for(i in 1:50){B=c(B,sample(1:49,size=6,replace=FALSE))}
+ B=B[-1]
+ S[s]=sum(B%in%(1:6))
+ }
> mean(S)
[1] 36.7694

But here for the top 6, we have

> z=TN[nb]
> sum(rev(z)[1:6])
[1] 29

i.e. the top 6 appeared 29 times over 50 draw of 6 balls (which looks low) and for the worst 6, it is a bit higher,

>  sum(z[1:6])
[1] 38

If we look at the theoretical density of the frequency of 6 given number, we have

i.e. our worst 6 is a nice average (in green) while top 6 did not appear frequently this time (here in blue) ! So we could not have used that information….
Anyway, if some of you are interesting using statistics to get a free lunch, with the nouveau loto, I did not see any strange pattern (data can be downloaded here).

I am terribly sorry, but I cannot help anyone winning at the French Lottery….

Detecting distributions with infinite mean

In a post I published a few month ago (in French, here, based on some old paper,there), I mentioned a statistical procedure to test if the underlying distribution https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO02.pngof an i.i.d. sample https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO01.png had a finite mean (based on extreme value results). Since I just used it on a small dataset (yes, with real data), I decided to post the R code, since it is rather simple to use. But instead of working on that dataset, let us see what happens on simulated samples. Consider https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO03.png=200 observations generated from a Pareto distribution

https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO04.png

(here https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO05.png=2, as a start)

> a=2
> X=runif(200)^(-1/a)

Here, we will use the package developped by Mathieu Ribatet,

> library(RFA)
  • Using Generalized Pareto Distribution (and LR test)

A first idea is to fit a GPD distribution on observations that exceed a threshold https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO11.png>1.
Since we would like to test https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO06.png (against the assumption that the expected value is finite, i.e. https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO07.png), it is natural to consider the likelihood ratio

https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO08.png

Under the null hypothesis, the distribution of https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO09.png should be chi square distribution with one degree of freedom. As mentioned here, the significance level is attained with a higher accuracy by employing Bartlett correction (there). But let  us make it as simple as possible for the blog, and use the chi-square distribution to derive the p-value.
Since it is rather difficult to select an appropriate threshold, it can be natural (as in Hill’s estimator) to consider https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO10.png, and thus, to fit a GPD on the https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO13.pnglargest values. And then to plot all that on a graph (like the Hill plot)

> Xs=rev(sort(X))
> s=0;G=rep(NA,length(Xs)-14);Gsd=G;LR=G;pLR=G
> for(i in length(X):15){
+ s=s+1
+ FG=fitgpd(X,Xs[i],method="mle")
+ FGc=fitgpd(X,Xs[i],method="mle",shape=1)
+ G[s]=FG$estimate[2]
+ Gsd[s]=FG$std.err[2]
+ FGc$fixed
+ LR[s]=FGc$deviance-FG$deviance
+ pLR[s]=1-pchisq(LR[s],df=1)
+ }

Here we keep the estimated value of the tail index, and the associated standard deviation of the estimator, to draw some confidence interval (assuming that the maximum likelihood estimate is Gaussian, which is correct only when n is extremely large). We also calculate the deviance of the model, the deviance of the constrained model (https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO06.png), and the difference, which is the log likelihood ratio. Then we calculate the p-value (since under https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO12.png the likelihood ratio statistics has a chi-square distribution).
If https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO05.png=2, we have the following graph, with on top the p-value (which is almost null here), the estimation of the tail index he https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO13.png largest values (and a confidence interval for the estimator),

If https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO05.png=1.5 (finite mean, but infinite variance), we have

i.e. for those two models, we clearly reject the assumption of infinite mean (even if https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO05.png gets too close from 1, we should consider thresholds large enough). On the other hand, if https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO05.png=1 (i.e. infinite mean) we clearly accept the assumption of infinite mean (whatever the threshold),

  • Using Hill’s estimator

An alternative could be to use Hill’s estimator (with Alexander McNeil’s package). See here for more details on that estimator. The test is simply based on the confidence interval derived from the (asymptotic) normal distribution of Hill’s estimator,

> library(evir)
> Xs=rev(sort(X))
> HILL=hill(X)
> G=rev(HILL$y)
> Gsd=rev(G/sqrt(HILL$x))
> pLR=1-pnorm(rep(1,length(G)),mean=G,sd=Gsd)

Again, if https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO05.png=2, we clearly rejct the assumption of infinite mean,

and similarly, if https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO05.png=1.5 (finite mean, but infinite variance)

Here the test is more robust than the one based on the GPD. And if https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO05.png=1 (i.e. infinite mean), again we accept https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO12.png,

Note that if https://perso.univ-rennes1.fr/arthur.charpentier/latex/paretoRO05.png=0.7, it is still possible to run the procedure, and hopefully, it suggests that the underlying distribution has infinite mean,

(here without any doubt). Now you need to wait a few days to see some practical applications of the idea (there was on in the paper mentioned above actually, on business interruption insurance losses).

EM and mixture estimation

Following my previous post on optimization and mixtures (here), Nicolas told me that my idea was probably not the most clever one (there).
So, we get back to our simple mixture model,

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM01.png

In order to describe how EM algorithm works, assume first that both https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM02.png and  https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM03.pngare perfectly known, and the mixture parameter is the only one we care about.

  • The simple model, with only one parameter that is unknown

Here, the likelihood is

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM04.png

so that we write the log likelihood as

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM05.png

which might not be simple to maximize. Recall that the mixture model can interpreted through a latent variate https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM06.png (that cannot be observed), taking value when https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM07.png is drawn from https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM02.png, and 0 if it is drawn from https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM03.png. More generally (especially in the case we want to extend our model to 3, 4, … mixtures), https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM08.png and https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM09.png.
With that notation, the likelihood becomes

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM10.png

and the log likelihood

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM11.png

the term on the right is useless since we only care about p, here. From here, consider the following iterative procedure,
Assume that the mixture probability https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM13.png is known, denoted https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM12.png. Then I can predict the value of https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM06.png (i.e. https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM08.png and https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM09.png) for all observations,

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM14.png

So I can inject those values into my log likelihood, i.e. in

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM15.png

having maximum (no need to run numerical tools here)

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM16.png

that will be denoted https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM17.png. And I can iterate from here.
Formally, the first step is where we calculate an expected (E) value, where https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM18.pngis the best predictor of https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM19.png given my observations (as well as my belief in https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM13.png). Then comes a maximization (M) step, where using https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM06.png, I can estimate probability https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM13.png.

  • A more general framework, all parameters are now unkown

So far, it was simple, since we assumed that https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM02.png and  https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM03.png were perfectly known. Which is not reallistic. An there is not much to change to get a complete algorithm, to estimate https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM30.png. Recall that we had https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM18.png which was the expected value of Z_{1,i}, i.e. it is a probability that observation i has been drawn from https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM02.png.
If https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM18.png, instead of being in the segment https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM31.png was in https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM32.png, then we could have considered mean and standard deviations of observations such that https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM18.png=0, and similarly on the subset of observations such that https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM18.png=1.
But we can’t. So what can be done is to consider https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM18.png as the weight we should give to observation i when estimating parameters of https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM02.png, and similarly, 1-https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM18.pngwould be weights given to observation i when estimating parameters of https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM03.png.
So we set, as before

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM33.png

and then

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM34.png
https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM35.png

and for the variance, well, it is a weighted mean again,

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM36.png
https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM37.png

and this is it.

  • Let us run the code on the same data as before

Here, the code is rather simple: let us start generating a sample
> X1 = rnorm(n,0,1)
> X20 = rnorm(n,0,1)
> Z  = sample(c(1,2,2),size=n,replace=TRUE)
> X2=4+X20
> X = c(X1[Z==1],X2[Z==2])
then, given a vector of initial values (that I called https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM12.png and then https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM99.png before),
>  s = c(0.5, mean(X)-1, var(X), mean(X)+1, var(X))
I define my function as,
>  em = function(X0,s) {
+  Ep = s[1]*dnorm(X0, s[2], sqrt(s[4]))/(s[1]*dnorm(X0, s[2], sqrt(s[4])) +
+  (1-s[1])*dnorm(X0, s[3], sqrt(s[5])))
+  s[1] = mean(Ep)
+  s[2] = sum(Ep*X0) / sum(Ep)
+  s[3] = sum((1-Ep)*X0) / sum(1-Ep)
+  s[4] = sum(Ep*(X0-s[2])^2) / sum(Ep)
+  s[5] = sum((1-Ep)*(X0-s[3])^2) / sum(1-Ep)
+  return(s)
+  }
Then I get https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM12.png, or https://perso.univ-rennes1.fr/arthur.charpentier/latex/mixEM99.png. So this is it ! We just need to iterate (here I stop after 200 iterations) since we can see that, actually, our algorithm converges quite fast,
> for(i in 2:200){
+ s=em(X,s)
+ }

Let us run the same procedure as before, i.e. I generate samples of size 200, where difference between means can be small (0) or large (4),

Ok, Nicolas, you were right, we’re doing much better ! Maybe we should also go for a Gibbs sampling procedure ?… next time, maybe….

Optimization and mixture estimation

Recently, one of my students asked me about optimization routines in R. He told me he that R performed well on the estimation of a time series model with different regimes, while he had trouble with a (simple) GARCH process, and he was wondering if R was good in optimization routines. Actually, I always thought that mixtures (and regimes) was something difficult to estimate, so I was a bit surprised…

Indeed, it reminded me some trouble I experienced once, while I was talking about maximum likelihooh estimation, for non standard distribution, i.e. when optimization had to be done on the log likelihood function. And even when generating nice samples, giving appropriate initial values (actually the true value used in random generation), each time I tried to optimize my log likelihood, it failed. So I decided to play a little bit with standard optimization functions, to see which one performed better when trying to estimate mixture parameter (from a mixture based sample). Here, I generate a mixture of two gaussian distributions, and I would like to see how different the mean should be to have a high probability to estimate properly the parameters of the mixture.

The density is here https://perso.univ-rennes1.fr/arthur.charpentier/latex/mix-ml-01.png proportional to

https://perso.univ-rennes1.fr/arthur.charpentier/latex/mix-ml-02.png

The true model is https://perso.univ-rennes1.fr/arthur.charpentier/latex/mix-ml-03.png, and https://perso.univ-rennes1.fr/arthur.charpentier/latex/mix-ml-04.png being a parameter that will change, from 0 to 4.
The log likelihood (actually, I add a minus since most of the optimization functions actually minimize functions) is
> logvraineg <- function(param, obs) {
+ p <- param[1]
+ m1 <- param[2]
+ sd1 <- param[3]
+ m2 <- param[4]
+  sd2 <- param[5]
+  -sum(log(p * dnorm(x = obs, mean = m1, sd = sd1) + (1 – p) *
+ dnorm(x = obs, mean = m2, sd = sd2)))
+  }
The code to generate my samples is the following,
>X1 = rnorm(n,0,1)
> X20 = rnorm(n,0,1)
> Z  = sample(c(1,2,2),size=n,replace=TRUE)
> X2=m+X20
> X = c(X1[Z==1],X2[Z==2])
Then I use two functions to optimize my log likelihood, with identical intial values,
> O1=nlm(f = logvraineg, p = c(.5, mean(X)-sd(X)/5, sd(X), mean(X)+sd(X)/5, sd(X)), obs = X)
> logvrainegX <- function(param) {logvraineg(param,X)}
> O2=optim( par = c(.5, mean(X)-sd(X)/5, sd(X), mean(X)+sd(X)/5, sd(X)),
+   fn = logvrainegX)
Actually, since I might have identification problems, I take either https://perso.univ-rennes1.fr/arthur.charpentier/latex/mix-ml-05.png or https://perso.univ-rennes1.fr/arthur.charpentier/latex/mix-ml-06.png, depending whether https://perso.univ-rennes1.fr/arthur.charpentier/latex/mix-ml-07.png or https://perso.univ-rennes1.fr/arthur.charpentier/latex/mix-ml-08.png is the smallest parameter.

On the graph above, the x-axis is the difference between means of the mixture (as on the animated grap above). Then, the red point is the median of estimated parameter I have (here https://perso.univ-rennes1.fr/arthur.charpentier/latex/mix-ml-05.png), and I have included something that can be interpreted as a confidence interval, i.e. where I have been in 90% of my scenarios: theblack vertical segments. Obviously, when the sample is not enough heterogeneous (i.e. https://perso.univ-rennes1.fr/arthur.charpentier/latex/mix-ml-09.png and https://perso.univ-rennes1.fr/arthur.charpentier/latex/mix-ml-04.png rather different), I cannot estimate properly my parameters, I might even have a probability that exceed 1 (I did not add any constraint). The blue plain horizontal line is the true value of the parameter, while the blue dotted horizontal line is the initial value of the parameter in the optimization algorithm (I started assuming that the mixture probability was around 0.2).
The graph below is based on the second optimization routine (with identical  starting values, and of course on the same generated samples),

(just to be honest, in many cases, it did not converge, so the loop stopped, and I had to run it again… so finally, my study is based on a bit less than 500 samples (times 15 since I considered several values for the mean of my second underlying distribution), with 200 generated observations from a mixture).
The graph below compares the two (empty circles are the first algorithm, while plain circles the second one),

On average, it is not so bad…. but the probability to be far away from the tru value is not small at all… except when the difference between the two means exceeds 3…
If I change starting values for the optimization algorithm (previously, I assumed that the mixture probability was 1/5, here I start from 1/2), we have the following graph

which look like the previous one, except for small differences between the two underlying distributions (just as if initial values had not impact on the optimization, but it might come from the fact that the surface is nice, and we are not trapped in regions of local minimum).
Thus, I am far from being an expert in optimization routines in R (see here for further information), but so far, it looks like R is not doing so bad… and the two algorithm perform similarly (maybe the first one being a bit closer to the trueparameter).

La tarification avec SAS

En tarification, il est possible d’utiliser d’autres logiciels que R, en particulier, il semble que l’on puisse faire deux ou trois choses avec SAS…. J’en parle un peu car il semble  que, paradoxalement, les asssureurs préfèrent encore SAS à R (par exemple). Et comme plusieurs étudiants m’avaient demandé “et comment on fait avec SAS ?“. Bon, par contre je ne mets que les choses de base, parce que SAS est assez limité sur ce qu’il peut faire….

Pour suivre un peu le plan du cours, la première étape est de définir une variable d’exposition dans la table,

DATA contrats;
SET lib.contrats;
lnexpo = log(expo);
run;

Pour faire une régression de Poisson, ce n’est pas forcément compliqué,

PROC GENMOD DATA = base;
ODS OUTPUT ParameterEstimates=Genmod1_Param
           Type3=Genmod1_Var
           Modelfit=Genmod1_InfoModele; 
MODEL nbsin = ageconducteur /
                  dist = poisson   
                  link = log   
                  offset = lnexpo 
                  type3;
RUN; QUIT;

La sortie SAS a alors l’allure suivante

                                  The GENMOD Procedure
                    Critère pour évaluer la qualité de l'ajustement
              Critère                   DF          Valeur       Valeur/DF
              Deviance                63E3      26872.5334          0.4237
              Scaled Deviance         63E3      26872.5334          0.4237
              Pearson Chi-Square      63E3      73275.5362          1.1553
              Scaled Pearson X2       63E3      73275.5362          1.1553
              Log Likelihood                   -18474.2667

       Algorithm converged.
                       Analyse des résultats estimés de paramètres

                              Erreur      Wald 95Limites
Paramètre    DF   Estimation   standard      de confiance %    Khi 2   Pr > Khi 2
Intercept     1      -3.5164     0.0851    -3.6832  -3.3496   1708.02       <.0001
ageconducteur 1       0.0168     0.0014     0.0141   0.0195    146.73       <.0001
Scale         0       1.0000     0.0000     1.0000   1.0000
NOTE: The scale parameter was held fixed.

                         Statistiques LR pour Analyse de Type 3
                      Source           DF      Khi 2    Pr > Khi 2
                      ageconducteur     1     148.72        <.0001

Il est aussi possible de faire des GAM (i.e. du lissage de la variable explicative – continue – avec des fonctions splines)

PROC GAM DATA = base;
MODEL nbsin = spline(ageconducteur) / dist = Poisson;
OUTPUT OUT=gam PREDICTED; 
RUN; QUIT;
PROC SORT DATA = gam NODUPKEY; BY age_cond; RUN; QUIT;

et on peut faire des prédictions avec ce modèle (la sortie n’apporte pas grand chose, en pratique),

DATA gam;
SET gam;
pred_nbsin_gam = exp(P_nbsin);
KEEP ageconducteur pred_nbsin_gam;
RUN;

Enfin, on peut tenter de faire un joli graphique. Pour cela, on calcule les prédictions de trois modèles, le premier étant des nombres moyens de sinistres par âge

PROC SORT DATA = base; BY ageconducteur; RUN; QUIT;
PROC MEANS DATA = base NOPRINT;
BY ageconducteur;
VAR nbsin;
WEIGHT expo;
OUTPUT OUT = nbsin_age (DROP = _TYPE_ _FREQ_) MEAN=mo
y_uni_nbsin;
RUN; QUIT;

ensuite, on fait un modèle GLM, et  un modèle GAM, et on récupère les sorties

PROC SORT DATA = nbsin_age; BY age_cond; RUN; QUIT;
PROC SORT DATA = gam; BY age_cond; RUN; QUIT;
DATA nbsin_age;
MERGE nbsin_age
      gam;
BY age_cond;
RUN;

On essaye de faire le dessin (je passe les lignes de commande, il y en a une vingtaine)

Pour faire une régression quasiPoisson, le code a l’allure suivante,s

PROC GENMOD DATA = base;
ODS OUTPUT ParameterEstimates=Genmod1bis_Param
           Type3=Genmod1bis_Var
           Modelfit=Genmod1bis_InfoModele; 
MODEL nbsin = ageconducteur /
                 dist = poisson  
                 link = log      
                 offset = lnexpo 
                 type3           
                 scale = deviance;
RUN; QUIT;

La sortie donne alors l’estimation du paramètre de surdispersion (ou sur cet exemple de sousdispersion)

                      Analyse des résultats estimés de paramètres

                                   Erreur    Wald 95Limites
Paramètre      DF   Estimation   standard    de confiance %     Khi 2   Pr > Khi 2

Intercept        1     -3.5164     0.0554  -3.6249  -3.4078   4031.29       <.0001
ageconducteur    1      0.0168     0.0009   0.0150   0.0186    346.32       <.0001
Scale            0      0.6509     0.0000   0.6509   0.6509

On notera que pour calculer le critère d’Akaike, ça n’est pas forcément trivial,

%MACRO CALCUL_AIC_BIC(infomodel=, param=);
    DATA _null_;
    SET &infomodel.;
    IF Criterion = "Log Likelihood" THEN CALL SYMPUT("Loglike", Value);
    IF Criterion = "Deviance" THEN CALL SYMPUT("n_etoile", Df);
    RUN;
    DATA _null_;
    SET &param.  end=fin;
    RETAIN nb_df 0;
    nb_df = nb_df + df;
    IF fin THEN CALL SYMPUT("k", nb_df);
    RUN;
    DATA genmod_aic_bic;
    SET &param.;
    FORMAT Loglike 12.2 K 10. N 10. AIC_CALC 12.2 BIC_CALC 12.2;
    Loglike = 0; K = 0; N = 0; AIC_CALC = 0; BIC_CALC = 0;
    IF Parameter = "Intercept";
    KEEP Loglike K N AIC_CALC BIC_CALC;
    RUN;
    DATA genmod_aic_bic;
    SET genmod_aic_bic;
    Loglike = &loglike.;
    K = &k.;
    N = %eval(&n_etoile. + &k.);
    AIC_CALC = 2 * Loglike + 2 * K;
    BIC_CALC = 2 * Loglike + K * log(N);
    RUN;
    PROC PRINT DATA = genmod_aic_bic;
    RUN; QUIT;
%MEND CALCUL_AIC_BIC;
%CALCUL_AIC_BIC(infomodel=Genmod2_InfoModele, param=Genmod2_Param);

Acheter des pochettes Pokemon ? et puis quoi encore !

Il y a quelque temps, Olivier Gergaud était venu à Rennes présenter son papier Stardom and Perceived Talent.Nous en avions profité pour discuter un peu d’un ancien papier qu’il avait fait sur les Pokemon (ici). Il faut avouer que je suis un peu jaloux car il essaye de répondre à une question que je me posais: le prix des cartes Pokemon a-t-il un lien avec les “pouvoirs” de la carte ou sa rareté.

Mais aujourd’hui je voulais répondre à une question simple que je me pose depuis que mon fils me dit (sans grand succès) “Papa, achète moi des cartes Pokemon” (ou “Naruto“, ou je ne sais quoi encore). Mon argument, en tant que père rationnel, est que ces cartes couchent très chers. Aujourd’hui, je vais le prouver. Supposons qu’il existe 200 cartes distinctes, et que ces cartes sont vendus 5 euros le paquet de 10. Pour simplifier, supposons que ces cartes soient vendues individuellement dans des cachés hermétiques à 50 centimes pièce. On va supposer que les cartes soient équi-réparties. Supposons que je puisse acheter une vignette spécifique (par exemple en ligne), dont je connais le personnage, pour 1 euro (soit le double du prix si le personnage est inconnu à l’achat). Quelle stratégie doit-je adopter ? et combien ça va me coûter ?
Je note https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-17.png le nombre de carte total (ici 200 car je suppose qu’il existe 200 personnages). Je note https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-01.png le coût d’une carte cachée (50 centimes ici) et https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-02.png le coût d’une carte non-cachée (1 euro). Supposons que j’ai à en ma possession les cartes https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-03.png (et que je n’ai pas les suivantes). Si je veux récupérer une nouvelle carte (que je noterais https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-05.png), en achetant au hasard i.e. dans des sachets hermétiques, le nombre de cartes à acheter est https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-06.png, qui suit une loi géométrique, de paramètre https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-07.png, où

https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-08.png

Par exemple, si j’ai https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-09.pngcartes, et qu’il m’en manque simplement une, alors la probabilité de la tirer est

https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-10.png

Pour revenir au tirage d’une nouvelle carte que je n’avais pas (alors que j’en https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-04.png), le coût moyen de ma stratégie est

https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-11.png

J’ai donc intérêt à acheter cette carte directement dès lors que

https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-12.png

ce qui devient intéressant dès lors que

 https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-13.png

Dans mon exemple numérique, https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-02.png étant le double de https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-01.png, je commence à acheter directement dès lors que j’ai en ma possession 100 cartes distinctes. Le coût moyen est alors

https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-14.png

Aussi, dans le cas que j’évoquais, on obtient 171€,
> .5*sum(200/(200-(1:101)-1))+1*(200-101+1)
[1] 171.0933

Je peux comparer à deux stratégies que l’on connaît. La première est de tout acheter à un collectionneur (i.e. à découvert, ce qui limite l’intérêt du “jeu“, j’en conviens). Dans ce cas, le coût total sera

https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-21.png

soit 200€. L’autre stratégie est d’acheter continuellement des paquets clos chez mon buraliste. Dans ce cas, le coût moyen serait

https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-16.png

Le calcul exact donne ici 587,80€, comme  le montre le calcul ci-dessous,
> 0.5*200*sum(1/1:200)
[1] 587.8031

mais on peut aussi utiliser une approximation de la forme

https://perso.univ-rennes1.fr/arthur.charpentier/latex/poke-22.png

(ce qui donnerait 529€ environ). Pour ceux qui ont besoin de voir pour croire, j’ai représenté ci-dessous le prix en fonction du moment où je décide de passer des cartes fermées aux cartes visibles.

Ça y est, j’ai enfin un argument rationnel à faire valoir à mon fils…. même si je ne suis pas certain de réussir à le convaincre aussi facilement…

Séminaire Probabilité et Statistique, UBO, Brest

Talk at the statistical seminar at the Université de Bretagne Occidentale, in Brest, Wednesday May 6th Tuesday May 5th, 14h (in  10 days), on “multivariate extremes“. Slides can be found here.

The talk will give a detailed introduction on multivariate extremes and related concepts. Then the case of Archimedean copula will be fully described (following the paper with Johan Segers).

[04/05/2009]: some applications in risk management will be shown at the end of talk, as well as some news things on spatial correlation.

and in order to illustrate tail convergence of Archimedean copulas, I have uploaded two animations, with tail independence below,

with tail dependence (or asymptotic dependence),

Méthodes numériques et convolution, suite

Pour poursuivre un ancien billet, je voulais revenir plus particulièrement sur l’algorithme de Panjer, et sur la précision de l’approximation faite en discrétisant la loi des coûts individuels. Les références sont ici

Je reprends ici un partie de l’article de wikipedia sur le sujet. Comme toujours, on souhaite approcher la loi de

 S = \sum_{i=1}^N X_i\,

On suppose ici que les coûts individuels sont discrets, et on pose

f_k = P[X_i = hk].\,

On suppose de plus que les nombres sont dans une classe un peu particulière, vérifiant

 P[N=k] = p_k=

En fait, cette condition n’est pas trop forte, la plupart des lois classiques étant de ce type.

La formule permettant d’obtenir

g_k =P[S = hk] \,.

est alors obtenue par récurrence, en posant

g_0=p_0\cdot \exp(f_0 b)\text{ if }a = 0,\,

g_0=\frac{p_0}{(1-f_0a)^{1+b/a}}\text{ for }a \ne 0,\,

et ensuite

g_k=\frac{1}{1-f_0a}\sum_{j=1}^k \left( a+\frac{b\cdot j}{k} \right) \cdot f_j \cdot g_{k-j}.\,

L’avantage c’est que tout cela a été programmé sous R… Pour la discrétisation, je reprends ici actuar qui propose plusieurs techniques. En particulier on distinguera entre une borne supérieure et une borne inférieure, une version arrondir et une version sans biais.

> fx <- discretize(pgamma(x, 2, 1), method = "upper", from = 0, to = 17, step = 0.5)
> fx <- discretize(pgamma(x, 2, 1), method = "lower", from = 0, to = 17, step = 0.5)
> fx <- discretize(pgamma(x, 2, 1), method = "rouding", from = 0, to = 17, step = 0.5)
> fx <- discretize(pgamma(x, 2, 1),method = "unbiased", lev = levgamma(x, 1), from = 0, to = 17, step = 0.5)

On peut alors utiliser l’algorithme de Panjer pour calculer la loi composée basée sur ces discrétisations. Au niveau de la programmation, le code est le suivant 

>  fx <- discretize(pgamma(x, 2, 1), from = 0, to = 22,
+  step = 0.5, method = "unbiased", lev = levgamma(x,2, 1))
>  Fs <- aggregateDist("recursive", model.freq = "poisson",
+  model.sev = fx, lambda = 10, x.scale = 0.5)

Graphiquement, on obtient la distribution suivante pour la loi composée (fonction de répartition et fonction quantile).